What Scrape.do provides
Scrape.do provides proxy-backed web scraping and specialised ready-made data APIs.
Its Google Search API returns structured organic results, ads, knowledge graphs, local listings, AI Overviews and other result types with advanced localisation.
Where the redirect matters
The destination URL is a core output. If Google exposes an opaque /goto token rather than the publisher URL in result markup, the service must follow or otherwise resolve that intermediary before returning the link customers expect. At scale, an extra operation per result can increase latency, failure rates and collection cost even when the public API schema stays the same.
/goto?url=[hash]resolve + attributepublisher URL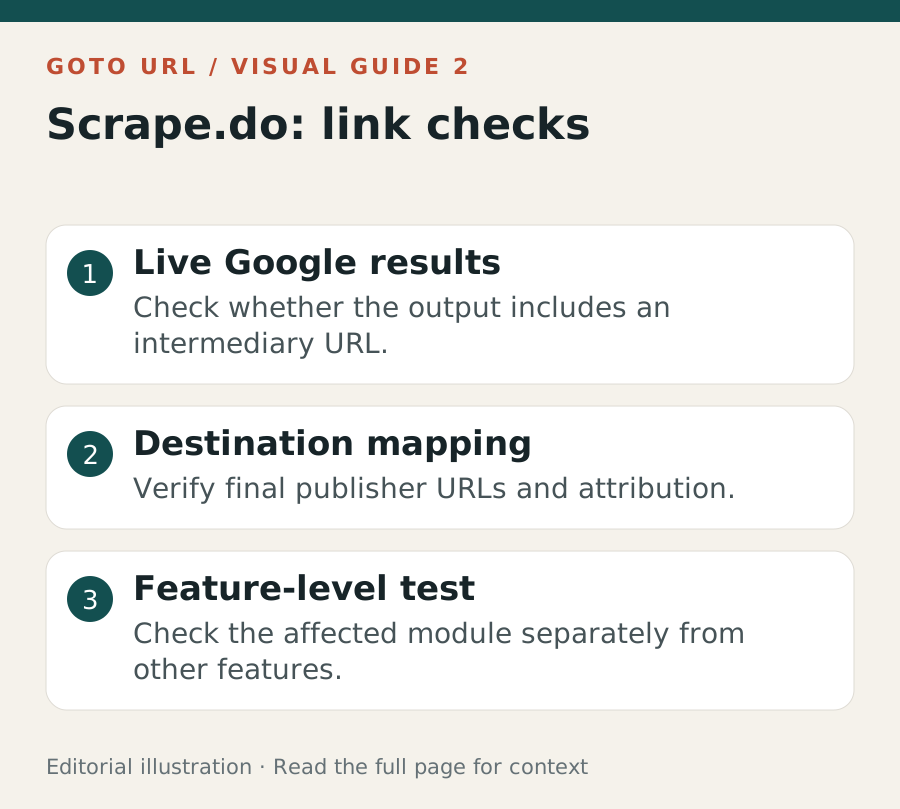
What Scrape.do has said
No public /goto response foundNo indexed, provider-owned page or attributable public statement from Scrape.do specifically addressing Google’s /goto rollout was located by 13 September 2026. Social or support updates may be unindexed or account-only.
A managed API can keep returning publisher URLs by following each redirect, extracting the destination from another Google response field, or relying on an upstream resolver. A normal-looking response does not by itself show that every result type is complete.
There is no provider-specific /goto test, incident record or resolution benchmark to validate. Scrape.do may be operating normally, but silence cannot establish unaffected status or reveal which data path it uses.
No /goto-specific price, quota, refresh-frequency or result-depth change was found. That does not show internal costs are unchanged: a provider could absorb them, reduce margin or alter collection without a public pricing notice.
No provider-specific /goto release or attributable statement is linked because none was found in the public review.
What is known — and what is not
Direct technical exposure is supported by the provider’s own description of collecting Google result pages. Unless stated otherwise, no provider-specific outage or response has been verified; this is an architectural assessment, not a claim that its current output is wrong.
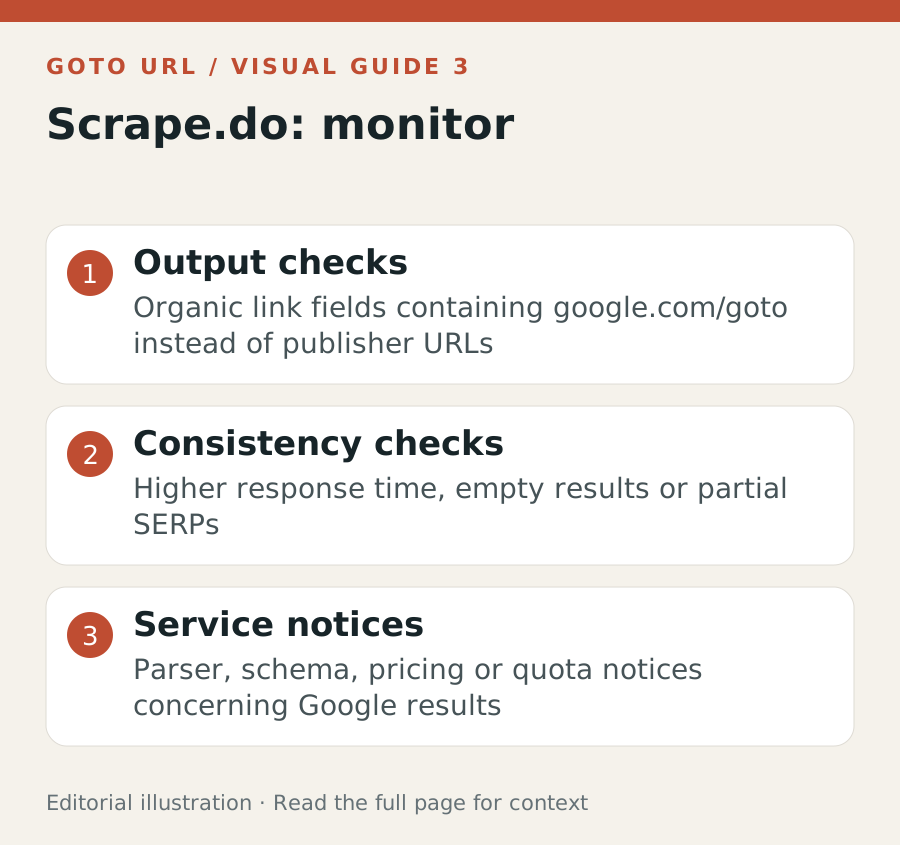
What customers should monitor
- Organic link fields containing google.com/goto instead of publisher URLs
- Higher response time, empty results or partial SERPs
- Parser, schema, pricing or quota notices concerning Google results
What should remain outside the change
- Non-Google sources where the redirect is not deployed
- Previously stored results that already contain resolved URLs